How the AI works
Specialized models read every upload: speech, faces, objects, on-screen text, actions, sound. This page is the tour of what happens under the hood, and why it makes every second findable.
On upload, the AI splits the audio and visual tracks and analyzes each one separately.
Specialized models handle three dimensions: sound (speech, music, effects), image (objects, faces, text on screen), and motion (actions and movement).
A final layer combines these signals into searchable concepts. One word, and you land on the right second.
Sound
Spoken words, music, ambient noise, mechanical sounds, applause. The AI transcribes speech, identifies speakers, and classifies non-speech audio, and makes all of it searchable.
Image
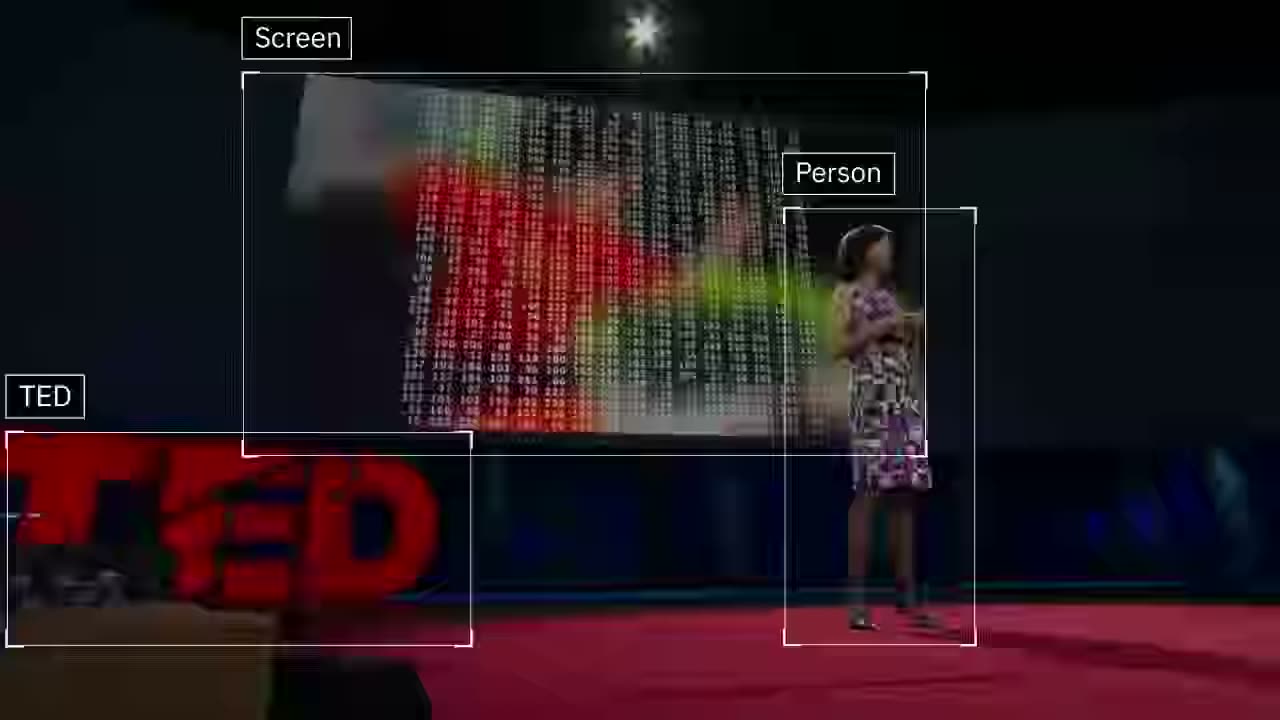
The AI recognizes objects, people, faces, text, logos, and colors: thousands of categories, timestamped in every frame.
Motion
Walking, running, gesturing, driving: the AI tracks movement across frames. Combined with sound and image data, it indexes what was happening in the video, not just what was visible in a single frame.
Concepts
Context resolves ambiguity. The AI understands related concepts, so searching "python" in a coding tutorial finds code, not snakes.
Find any moment.
Transcribed, labeled, and chaptered for you.
No setup. Upload a video and the AI does the rest.
Get started (it’s free)